
On teams that practice both CRO and branding every day, no one is really surprised that the two are linked.
A growth lead with some experience knows that a winning conversion test can get expensive three months later if it cut into what made the brand desirable.
A brand team that has launched a site before knows that an identity that refuses to face real usage ends up producing beautiful pages that no one converts on.
The fundamental disagreement, the one people love to describe at conferences, exists mostly in the heads of commentators who have never had to run both at the same time.
In practice, though, you regularly run into an organizational problem.
The CRO roadmap is decided in one meeting, the brand guidelines are defended in another, and the two teams rarely work from the same dashboard or on the same decision calendar. This split isn't ideological. It simply comes from how most companies structure their teams: a growth lead answers for a conversion number, a brand lead answers for a perception, and neither is really in charge of checking that one isn't eating into the other.
This governance gap then creates the impression of a conflict between two approaches that, at their core, are after exactly the same thing: understanding why a customer chooses, hesitates, comes back or gives up.
The two disciplines share a lot, and once the thinking reaches that level, you can start to see what separates them and what brings them together.
Both work from hypotheses tested against reality rather than pure intuition. Both accept that some of their bets will fail, whether a test that doesn't win or a brand campaign that does nothing for awareness, and neither treats that as a disaster.
And both are less interested in pleasing people than in understanding why customers act the way they do.
What sets them apart is mostly speed and the cost of a mistake.
A test that gets it wrong costs a few weeks of poorly used traffic, a reversible loss that can usually be measured precisely the following week. A decision that damages how people perceive a brand takes much longer to fix, because it affects trust built over several years, and a single reversal rarely repairs it.
This difference in cost, not in nature, is why decisions should be handled differently depending on what they put at stake, without ever pretending that one discipline matters more than the other.
An A/B test delivers clear proof in two to four weeks: a conversion gap, statistical significance, a curve that goes up or doesn't. That proof has a limit people rarely mention: it only looks at what happens during the test window, among the visitors who arrive during the test window.
If a variant slightly erodes the trust a customer places in the brand, that effect won't show up at D+14.
If you look for it, it shows up at D+90 or D+180: a slightly higher return rate, a slightly lower average order value among returning customers, an NPS that slips two points over a quarter.
This is a direct consequence of how A/B testing works statistically: to get enough power over a short window, you need a simple metric that sits close in time, and conversion ticks that box far better than brand perception does.
The companies that have already solved this problem didn't invent a new philosophy. They added a measurement tool.
In the experimentation literature, these are called “guardrail metrics”: indicators that aren't meant to be optimized but must stay stable, whatever the result of the main test.
Ron Kohavi, who led experimentation teams at Microsoft and then Airbnb before co-writing the leading book on the subject, describes these metrics as the safeguards that stop a test from winning on one criterion while quietly degrading something else.
At Airbnb, a test designed to increase bookings is also monitored for reported traveler satisfaction, so that a conversion gain isn't paid for with negative reviews a few weeks later.
At Netflix, a test on recommendations is monitored for streaming quality, for the same reason.
Nothing prevents applying exactly this logic to the brand rather than to satisfaction or technical quality: on tests judged to have a strong impact on identity, track one or two perception indicators, even rough ones, and reopen the file ninety days later instead of filing it as a success on day fourteen.
Booking.com shows what happens when a company pushes the logic of testing to its limit without having this kind of guardrail in place from the start.
The company built a particularly intense experimentation culture, documented in a Harvard Business School case study: thousands of simultaneous tests, and decentralization that lets any team launch a test without prior approval from management. There's also an anecdote often cited in the industry: the group's first American executive proposed a new logo when he arrived and was told it would be checked with a test first, with no exception allowed even for a choice so tied to identity.
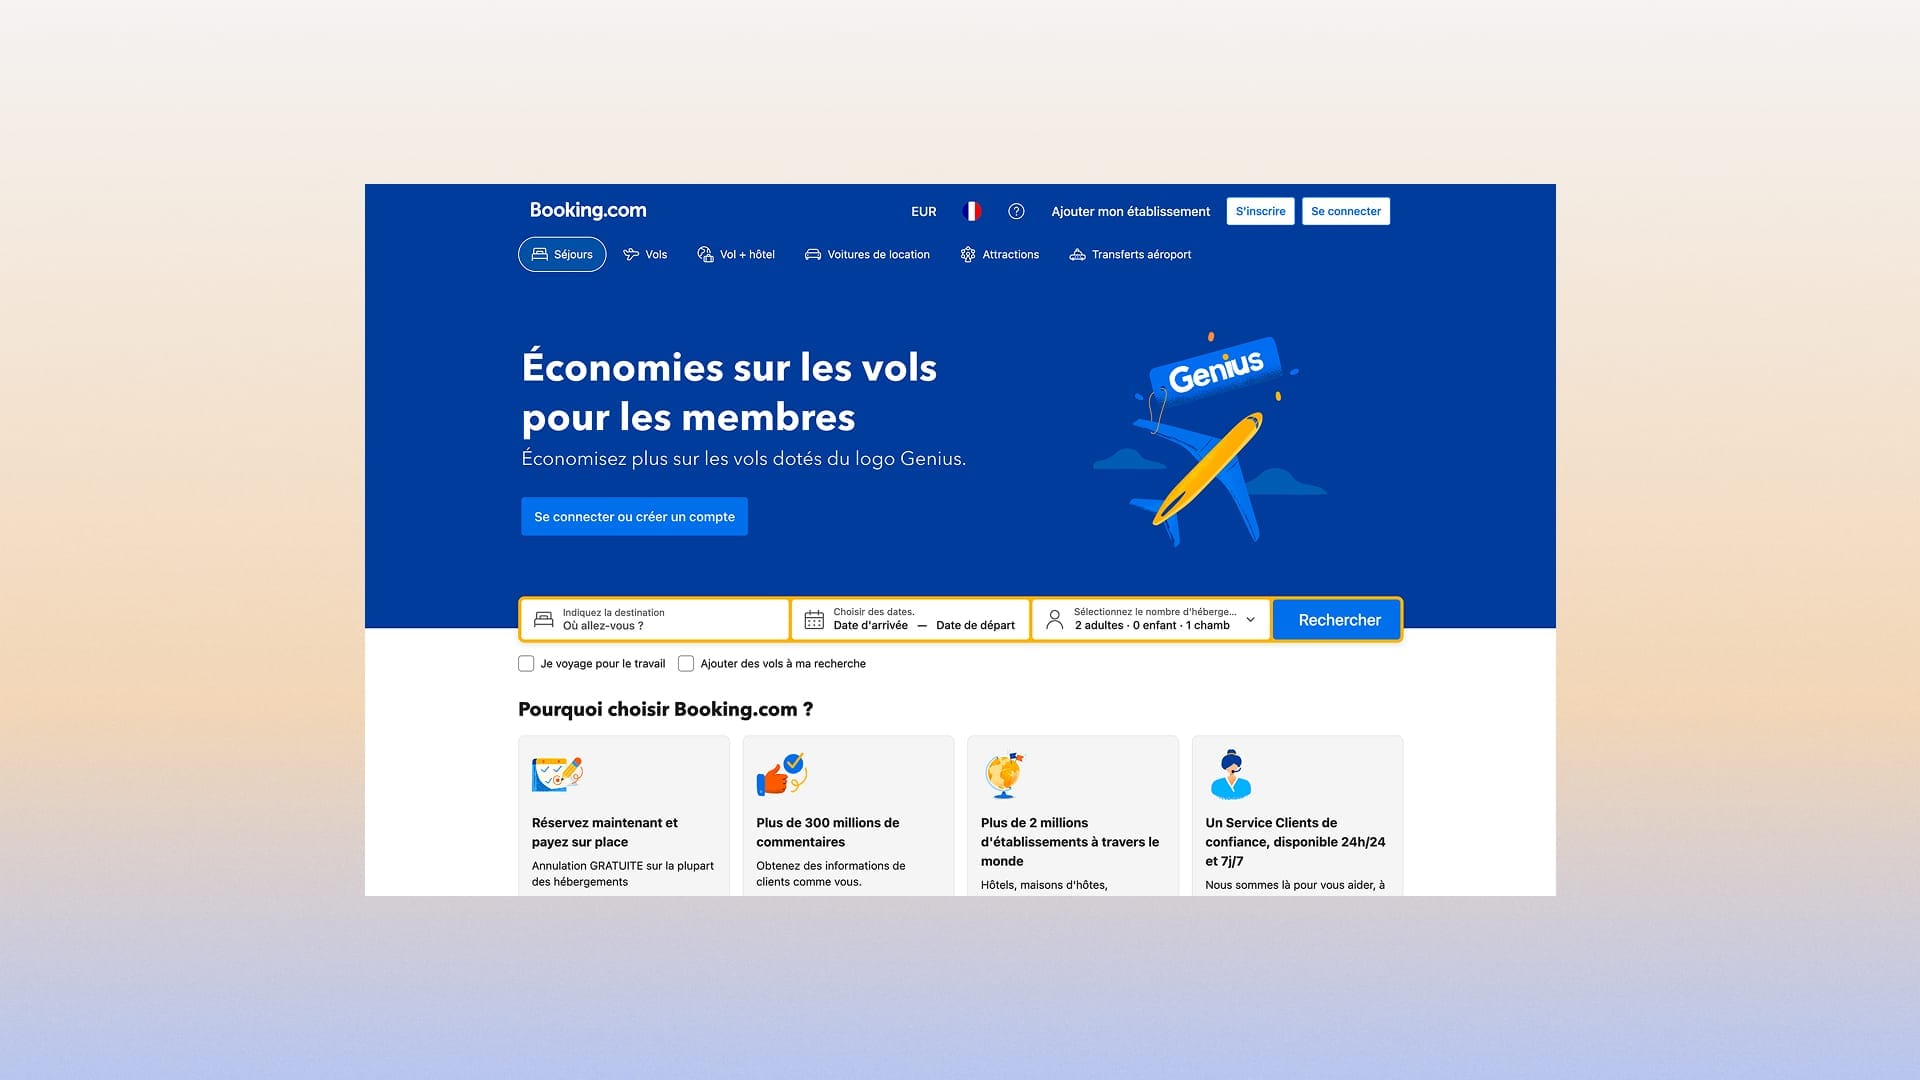
This discipline produced considerable commercial results. For several years, it also produced a pile-up of urgency banners, scarcity messages and reassurance popups, each validated on its own by a winning test, until the overall experience was regularly criticized as anxiety-inducing.
The UK competition authority eventually opened an investigation into commercial practices in online hotel booking, and in 2018 took action to end sales tactics it considered misleading.
Read more:
 Robin Marzin
The company has since moved part of its interface toward a more restrained design. That adjustment confirms, after the fact, exactly the point guardrail metrics are meant to address up front: a test can win very cleanly on conversion while damaging, over a longer period, something no one had put under watch.
What makes the case interesting, beyond the anecdote, is that Booking.com never gave up its testing culture.
The same study documents how the team handles its failures: rather than filing away a failed test, it tries to understand why, using qualitative interviews. A test that displayed the strength of a hotel's WiFi signal initially changed nothing in conversion, until the team found out, by interviewing travelers, that what mattered wasn't WiFi speed but what it made possible: watching a series without interruption, sending emails without waiting.
The next test, which talked about what WiFi made possible rather than its raw performance, worked.
This method of testing, seeing a failure and digging into why instead of moving on to the next test, is exactly the reflex that's most often missing when a test touches the brand: top-level data is never enough on its own, and it needs a qualitative reading of what it actually covers.
Glossier lets us look at the same problem from the other end.
The brand built minimalist product pages, with no countdown timers or last-minute popups, where every element is instantly recognizable. In a beauty segment where the average conversion rate in France is between 2.5% and 3.5%, it structurally outperforms that average without relying on the usual urgency mechanics. The reason is more about sequence than intensity: a large share of its customers have already decided to buy before they reach the product page, thanks to community and content work done upstream.
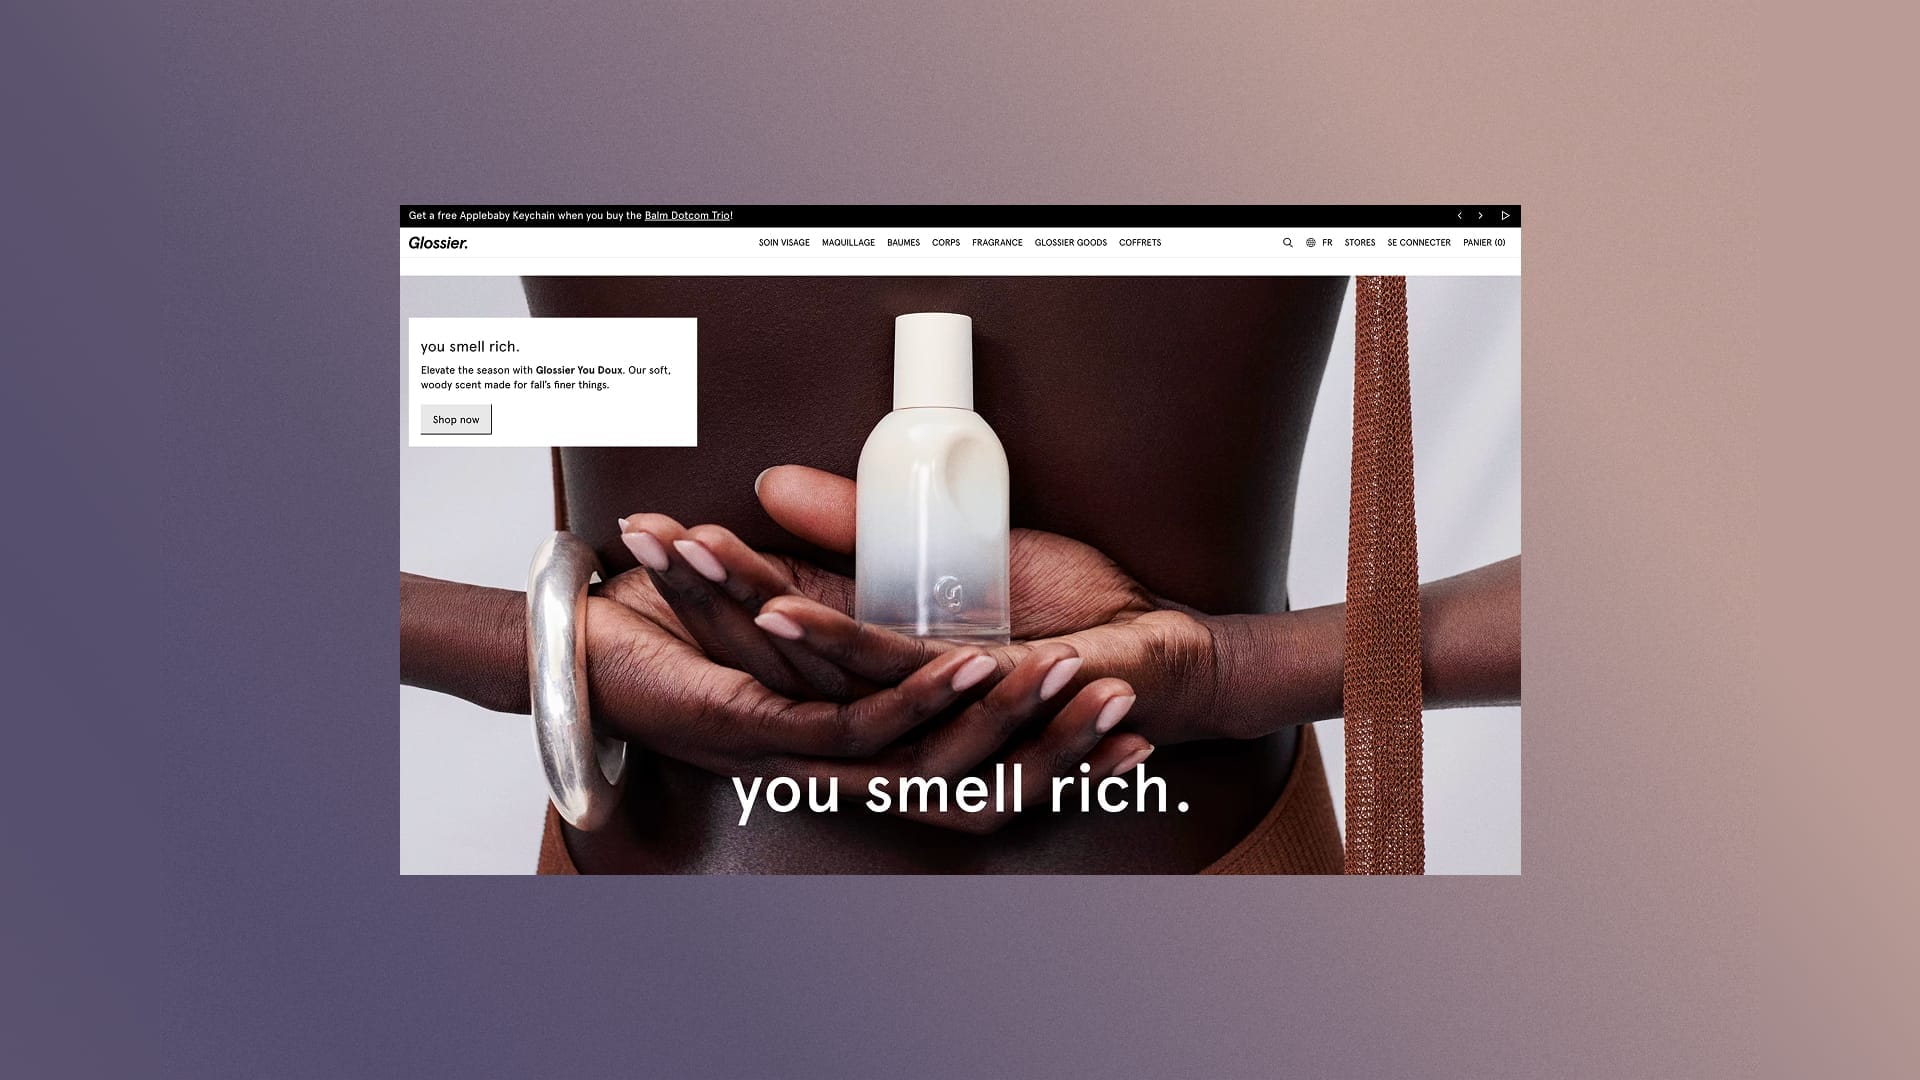
Emily Weiss, its founder, describes this shift in an interview with FrenchWeb, where she explains that the buying decision is built in the community rather than on the product page itself. CRO then has a precise role: removing leftover friction without having to make up for a conviction that has already formed elsewhere.
When the team wanted to test elements more directly focused on conversion, it chose to do so on isolated pages, outside the main site. That comes down to the same principle as the guardrail described above, put another way: separate the space where you can be wrong without consequences from the space where a mistake would be costly in the long run.
What Booking.com and Glossier show, each in their own way, is that neither discipline has to give up ground to the other for the two to move forward together.
What makes the difference is when you choose to look at what a test produces beyond its usual measurement window, and where you decide to set the line between what can be tested freely and what deserves closer monitoring.
In practice, for an e-commerce team that wants to apply this principle without overhauling its entire governance, three things are enough to get started:
- Before launching a testing program, name the two or three elements of your identity that you refuse to see degrade, even if a test wins on them.
- On tests that touch those elements, add one or two perception indicators tracked over several months rather than two weeks.
- Set a fixed moment, a quarter later for example, to reopen those tests and check that they still hold up once they're outside their statistical window.
The gap often comes down to how management and the decision-making chain are organized, and to internal organization and communication: deciding who reads the reports, how often, and with what authority.
It's a question of vision and governance before it's a question of method.
It explains why so few companies pull it off, less for lack of tools than from a reluctance to admit that neither team can, on its own, guarantee that the other is moving forward at the same pace.